
open-steps
Plain-language agent skills for Claude Code, Codex, Cursor and Gemini CLI: honest session reports, straight verdicts, steps you can follow. MIT.
 kharmanskyi
- 评测生成时间(北京时间)
- 本报告引擎
- v3.14.0
- 当前引擎
- v3.17.3
本报告与当前引擎使用不同规则;原分数不会自动更新,不同版本的分数不宜直接对比。
进入后确认来源与额度,提交才会创建任务。
代码版本未记录或记录无效,无法核对本报告的 commit 与送评文本;不会用当前项目代码回填历史记录。
综合采用结论
证据充分,整体质量与安全表现优秀
- 基础评测完成+25/25确定性评分与静态安全扫描已完成
- README 有效证据+25/2521,149 个去重后的有效字符
- 独立证据来源+20/205 类非重复证据,重复文件不叠加
- 仓库元数据+10/10已取得仓库状态与采用数据
- 活跃记录+5/5已取得最近提交时间
- AI 复核+15/15已完成结构化 AI 证据复核
本报告评了什么
综合分用于静态采用筛选,不是任务成功率,也不代表使用 Skill 后的能力提升。
- 静态检查范围
- 记录 9 个文件 · 75,963 字符
- 只检查采集到的受限文本与已知风险模式;未读取的脚本、依赖和运行环境不在结论内。
- AI 内容复核
- 已使用
- 复核送评文本的说明和设计,不是安装测试或实际任务执行。记录缺失时不推断已使用或未使用。
- 真实任务效果
- 本报告未提供实测证据
- 没有使用/不使用 Skill 的任务对照、重复运行或耗时与 token 成本结果。采用前仍需在隔离环境验证自己的任务。
脚本引用覆盖
脚本引用覆盖记录不可得;不推断没有引用或已经检查。
Open Steps 技能闭环与钩子
README 描述技能按工作顺序形成循环,并有 session-start 与 stop-report 两个钩子参与,属连续处理步骤
左右滑动查看完整图示
- • The skills 段:They work as a loop: os-whats-next picks the work, os-step-by-step walks you through your part, os-done-or-not reports the result, os-check-work ac
- • Optional pieces and limits:session-start.sh 注入路由表与上次报告,stop-report.sh 在会话结束时请求报告
- Quick start:claude plugin marketplace add ./open-steps && claude plugin install open-steps@open-steps
- Numbers 表:os-step-by-step 在 Haiku 4.5 仅 4/9,全 25 短语 85%/98%/100%
- Optional pieces and limits:OPEN_STEPS_COOLDOWN=900、OPEN_STEPS_MIN_FILES=1、OPEN_STEPS_DISABLE 等设置表
- How the pack is built:预批准仅限报告目录、gh pr 读取与 gh pr merge;自动合并已完成 PR
- Other agents:Codex/Cursor/Gemini CLI 安装命令与“how reliably the skills fire there is not checked”
- 问题与用途描述
- 有效 README
- 安装或接入步骤
- 可执行示例
- 未发现已知高风险模式
- README 自述并非每个技能都有 worked example
- Codex/Cursor/Gemini CLI 上技能触发可靠性声明为 not checked
- 770 tokens 会话开销数据在新增技能后未重测
- 自动合并已完成 PR 属高风险默认行为,仅靠任务备注或 CLAUDE.md 关闭
非工程背景、用 Claude Code 独立构建产品的个人、需要把 agent 会话结果转成可读报告与操作步骤的团队、希望用实测数据评估技能触发率的用户
不接受 agent 自动合并 PR 的团队、依赖 Codex/Cursor/Gemini CLI 且要求稳定自动触发的用户、需要完整逐技能示例文档的使用者
也有自己的公开项目?先免登录查已有报告;没有报告时,可保留地址继续登录评测。
查找我项目的报告 →静态扫描不是安全保证,生产接入前仍应人工复核权限和数据边界。
方法、证据与局限展开收起
GitHub Repository API
9 个文件 · 75,963 字符
v3.14.0 · AI 内容复核:已使用(deepseek-flash)
- 静态评测不会安装或执行项目代码
- 安全扫描基于高信号文件与已知模式,不能替代人工审计
- 流行度只反映采用程度,不代表安全或工程质量
30 天热度趋势
README
Open Steps

English · Español · Français · Русский · Українська · 한국어 · 中文
Plain-language agent skills for Claude Code, Codex, Cursor and Gemini CLI.
They keep development open to the person running it: the sessions, the decisions, the next steps, the whole picture.
I'm not an engineer. I'm a market-led builder: I look for where demand already exists and the infrastructure doesn't, then build the missing piece. Twenty years of building web and software products, always from the product side, and more than 50 developers at my company today.
Apart from the company, I started building a product on my own, just vibecoding. Partly to stay ahead of where all this is going, partly because I think the moment has arrived for people like me: you can now imagine a serious product and build it yourself, with no engineers or very few of them.
Then I ran straight into a wall. The agent does excellent work, then tells me about it in commit hashes and jargon, and I genuinely cannot tell whether we are done. Not because the work is unclear. Because nobody taught the agent to talk to someone who doesn't speak engineering.
So I built this pack. I'm sharing it here for anyone in the same position, and that's the whole idea behind the name: every step of building with an agent, kept open to the person doing the building. Right now it changes what the agent tells you. Where I want to take it next is the work itself, not just the reporting.
Before and after
The whole idea in one screen. Work ends, you ask "are we done?".
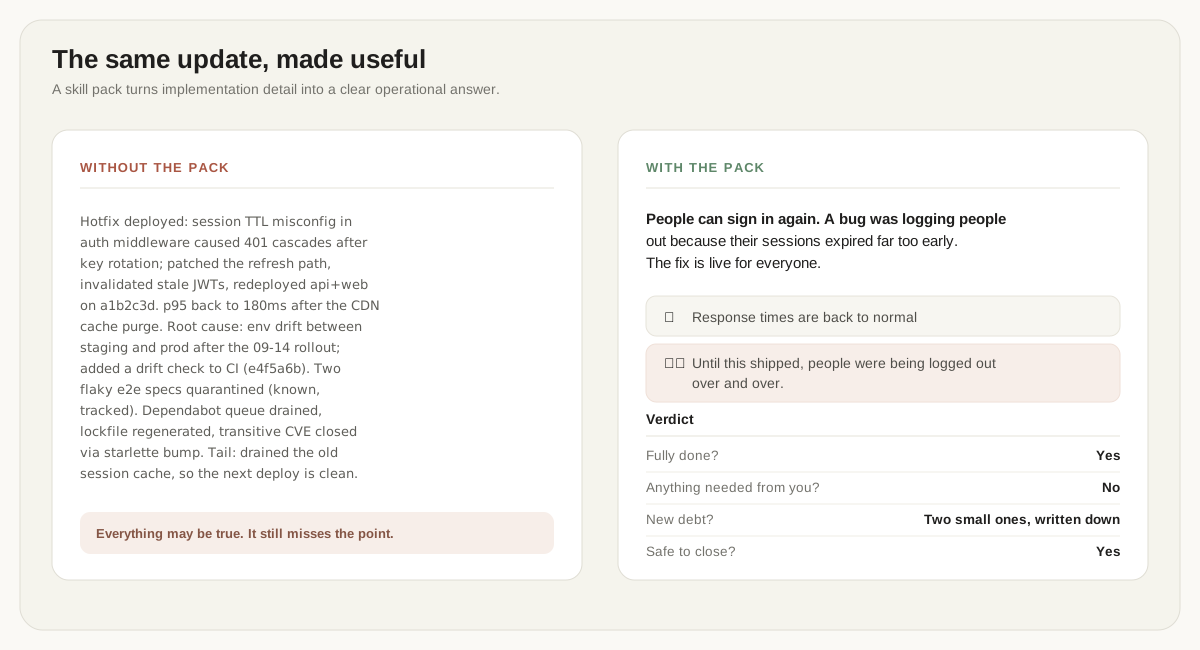
The same thing as text, if the picture does not load
Without the pack:
Hotfix deployed: session TTL misconfig in auth middleware caused 401 cascades after key rotation; patched the refresh path, invalidated stale JWTs, redeployed api+web. p95 back to 180ms. Root cause: env drift after the 09-14 rollout. Two flaky e2e specs quarantined (known, tracked)…
With it you get this:
People can sign in again. A bug was logging people out because their sessions expired far too early. The fix is live for everyone.
✅ Response times are back to normal ⚠️ Until this shipped, people were being logged out over and over.
Fully done? Yes Anything needed from you? No New debt? Two small ones, written down Safe to close? Yes
Same facts. One screen. The bad news gets its own row instead of hiding in
the middle of a paragraph. A second, longer example from a real session lives
in this repository, with notes on what the rewrite changed:
skills/os-done-or-not/references/01-prod-promote.md.
The skills
| Skill | What it does | When it fires |
|---|---|---|
os-done-or-not | A one-screen report with a verdict: done or not, anything needed from you, any new debt, safe to close | Work wraps up, or you ask how it went |
os-step-by-step | Numbered steps a non-technical person can follow. The agent must first try everything itself and ask only for what truly needs you | The agent needs you to run, paste, click, approve or test something |
os-ask-simple | The question in plain words, what it costs later, and one marked recommendation | The agent has a question or options for you |
os-what-could-go-wrong | Assumes the decision already failed and works backwards to find out why, in a fresh agent that had no hand in it. Ends on one verdict | Something hard to undo is about to be agreed: a contract, a purchase, a migration, a launch |
os-whats-next | Merges what is verified and ready, then recommends the next task and says why in plain words | You ask what is left or what to do next |
os-check-work | Does not trust another session's report. Checks every claim against what actually happened, then says what to do about it | Another session says it is done |
os-say-simple | Rewrites any text in plain words without losing facts or bad news. Give it a number and you get exactly that many points | Any text reads like engineering: a report, a comment, an error, the agent's own answer |
os-big-picture | Keeps one BIG-PICTURE.md: what the product is, every feature with how far it got, which parts nobody uses any more, and what is queued. It offers to open the queue as tickets in a tracker you already use | You ask where the project stands, or a session report was just written |
They work as a loop: os-whats-next picks the work, os-step-by-step walks
you through your part, os-done-or-not reports the result, os-check-work
accepts what other sessions did, os-ask-simple handles the questions on the
way, os-what-could-go-wrong attacks anything hard to undo before it is
agreed, and os-say-simple rescues any text that still reads like
engineering. os-big-picture keeps the standing file whose queue
os-whats-next reads as its backlog.
os-big-picture writes its file in plain words, so you get the whole picture
without reading code. It measures from git how old each part is and whether
anything still uses it, and it dates what it cannot measure. It opens tickets
in your tracker only after you say yes. The file stays out of your commits
unless you add it yourself. It never invents a task and never deletes
anything. The rules and the reasons behind them are in
skills/os-big-picture/.
What it does on its own
The pack finishes finished work by itself. If a pull request has green checks and an approved review, the agent verifies it once more and merges it. On Claude Code that happens without a permission prompt. On Codex CLI, Cursor CLI and Gemini CLI the merge command goes through that tool's own permission settings, per their documentation. Whatever unblocks the most goes first.
Two things stop a merge: a claim that fails verification, or a note on the
task saying merges happen on command only. Write that note on the task
wherever another tool or person decides when to merge. To have merges on
command only, put the same note in your standing instructions file:
~/.claude/CLAUDE.md, ~/.codex/AGENTS.md, ~/.gemini/GEMINI.md, or the
project's AGENTS.md on Cursor CLI.
On Claude Code a skill can also pre-approve tools for the turn it runs in,
through its allowed-tools field. This pack keeps that list to what the
skills use:
| Skill | Pre-approved on Claude Code |
|---|---|
| Every skill | Reading its reports folder, ~/.claude/open-steps/ |
os-done-or-not | Writing its report in that folder, and gh pr view and gh pr checks |
os-whats-next, os-check-work | gh pr list, gh pr view, gh pr checks and gh pr diff, which read a pull request, and gh pr merge, for the merges above |
os-big-picture | Editing its own BIG-PICTURE.md, its census script, git rev-parse --git-dir to find the repository folder, gh repo view, gh issue list, and gh issue create, which opens tickets after you say yes |
os-what-could-go-wrong | Its premortem prompt script |
/open-steps:os-install-check | doctor.sh |
Other commands, and files outside your project and the reports folder, go
through your own permission settings as usual. Other read-only git commands
need no entry, because Claude Code runs them without asking. Codex CLI, Cursor
CLI and Gemini CLI ignore the field, per their documentation, and
ask the way they normally do. That part has not been tested.
Install
The skills are the same folders on every tool. On Claude Code a plugin installs them and wires both hooks in one command. On Codex CLI, Cursor CLI and Gemini CLI one copy command installs the skills, and each tool takes a few lines of hook settings. What was run on each tool, and what comes from its documentation, is under What was run on each tool.
First, for any tool
You need git to download the pack and to update it. Some skills, such as
os-whats-next and os-check-work, also read project state through git and
gh, GitHub's command-line tool. gh is
optional. Without it, more of the output says "not checked".
Clone this repository:
git clone https://github.com/kharmanskyi/open-steps.git
Stay in the folder where you ran that command, the one that now holds
open-steps/. The commands below run from there. Only git pull runs inside
the clone.
On every tool you add one piece by hand: the routing block. The agent decides by itself whether to use a skill. The routing block is a short table that names the moments when it must use one, and which one. It goes in the file your tool reads as standing instructions, and each tool's part below names that file. Why the block matters.
The pack also has two hooks. One starts each session with the routing table and your last report. The other asks for a report when a session ends with real work done. How they work: The hooks.
Claude Code
Install the pack as a plugin. This wires the skills and both hooks:
claude plugin marketplace add ./open-steps && claude plugin install open-steps@open-steps
Check what you got:
claude plugin details open-steps
To check the whole install, not just the plugin, run
/open-steps:os-install-check in Claude Code. It reports what is wired and
what is not, and says "not checked" where it could not look.
The routing block goes in your own ~/.claude/CLAUDE.md, where it survives
long conversations. One command, from the same folder, safe to re-run:
grep -q 'os-done-or-not' ~/.claude/CLAUDE.md 2>/dev/null || cat open-steps/docs/routing-block.md >> ~/.claude/CLAUDE.md
To update: git pull inside open-steps/, then
claude plugin update open-steps@open-steps. Both steps are needed. The
plugin updates from your clone, not from GitHub. Without the pull it says
"already at the latest version" about an old copy. The installed copy changes
only when the pack's version number does.
To remove: claude plugin uninstall open-steps, then take the block back out
of your ~/.claude/CLAUDE.md.
The pack also has an optional output style for Claude Code, Answer first. It
makes the agent put the answer in the first line and stop narrating its
checks. It is off by default, because turning it on would replace a style you
already chose. Turning it on takes two lines, in
docs/output-style.md. Output styles are a Claude
Code setting, so the pack does not wire it on Codex CLI, Cursor CLI or Gemini
CLI.
Codex CLI, Cursor CLI and Gemini CLI
These three tools read ~/.agents/skills/, so one command installs the skills
for all of them:
mkdir -p ~/.agents/skills && cp -R open-steps/skills/os-* ~/.agents/skills/
The rest is set per tool:
| Codex CLI | Cursor CLI | Gemini CLI | |
|---|---|---|---|
| Routing block goes in | ~/.codex/AGENTS.md | AGENTS.md in the project root | ~/.gemini/GEMINI.md |
| Hooks go in | ~/.codex/config.toml. Per Codex's docs, it then asks once to trust them | ~/.cursor/hooks.json, through hooks/adapter.sh | ~/.gemini/settings.json, through hooks/adapter.sh, with the stop hook on AfterAgent |
| Check | bash open-steps/doctor.sh | bash open-steps/doctor.sh | bash open-steps/doctor.sh |
| Update | git pull inside open-steps/, then the copy command again | git pull inside open-steps/, then the copy command again | git pull inside open-steps/, then the copy command again |
| Remove | Delete the os-* folders from ~/.agents/skills/, the block from ~/.codex/AGENTS.md, and the two hook entries from ~/.codex/config.toml | Delete the os-* folders from ~/.agents/skills/, the block from AGENTS.md, and the two hook entries from ~/.cursor/hooks.json | Delete the os-* folders from ~/.agents/skills/, the block from ~/.gemini/GEMINI.md, and the two hook entries from ~/.gemini/settings.json |
The routing block command for each tool, safe to re-run, is in
docs/other-agents.md. So are the
hook settings, in The hooks there, and
everything that was run rather than read.
doctor.sh reads the shared skills folder and each tool's own, the routing
block, and the hook settings of each tool it finds, down to the event each
hook sits under. It says "not checked" for what it cannot look at.
The skills are a copy, so they stay as they were until you run the copy command again. The remove steps have not been run yet.
If you also use Claude Code in a project where the block sits in AGENTS.md
for Cursor CLI: Claude Code 2.1.277 and later reads a project's AGENTS.md
when the project has no CLAUDE.md, per its changelog. So the block reaches
Claude Code in that project too.
Numbers
The pack tells the agent to separate what it measured from what it assumed. Same rule for me. Twenty-five phrases a person would actually say, each asked three times with no one at the keyboard, on three Claude models: did the right skill switch on by itself? Three off-topic questions, asked the same way, checked the opposite. Three runs per phrase is a smoke test, not a benchmark.
The chart and the table are Claude Code. The same phrases were run on Codex CLI, Cursor CLI and Gemini CLI by contributors, and what each tool counts as "switched on", what was run on every tool, and what the misses show are in evals/README.md.
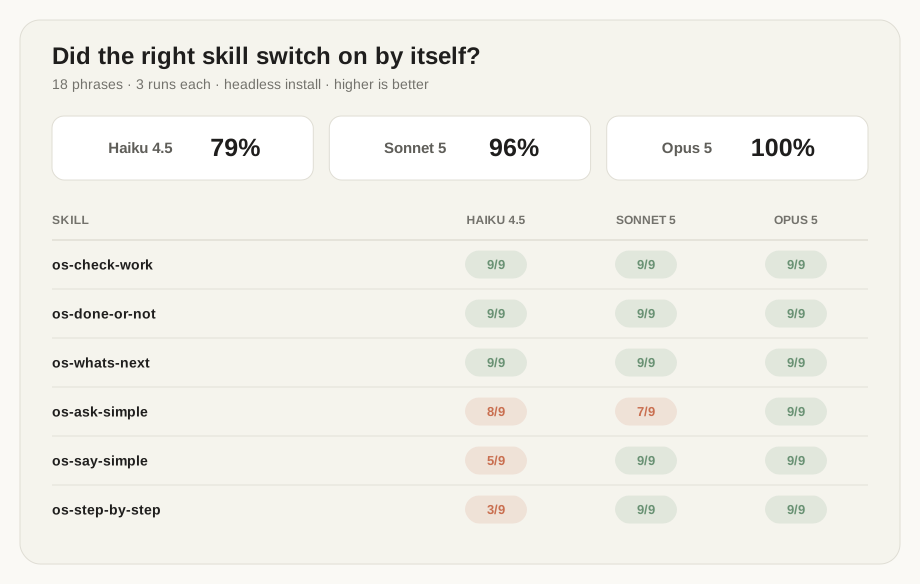
Measured on 2026-10-05.
| Skill | Haiku 4.5 | Sonnet 5.5 | Opus 5.5 |
|---|---|---|---|
os-done-or-not | 12/12 | 12/12 | 12/12 |
os-whats-next | 9/9 | 9/9 | 9/9 |
os-check-work | 9/9 | 9/9 | 9/9 |
os-ask-simple | 9/9 | 9/9 | 9/9 |
os-what-could-go-wrong | 9/9 | 9/9 | 9/9 |
os-big-picture | 9/9 | 9/9 | 9/9 |
os-say-simple | 7/9 | 9/9 | 9/9 |
os-step-by-step | 3/9 | 9/9 | 9/9 |
| All 25 phrases | 89% | 100% | 100% |
| Fired on an off-topic question | 0/9 | 0/9 | 0/9 |
Everything is in evals/: cases.md is every
phrase we ask, results.md is what came back, phrase by
phrase. The scorer writes that file; I don't type it. Scoring is a plain
script reading tool calls, with no AI judging anything. Re-run it with
bash evals/run.sh; EVAL_AGENT picks the tool, and a script for another
tool follows the contract in
Measuring another agent.
Also easy to check yourself: the pack's descriptions are always on, and Claude
Code estimates their cost itself. Run claude plugin details open-steps for
the current figure. The session-start hook adds its text on top: the routing
table, and the last report, capped by OPEN_STEPS_MAX_REPORT_LINES.
How the pack is built
Each skill is one folder with one SKILL.md inside: a short header, then the
rules. Each also has a worked example in its references/ folder.
What runs on your machine is plain shell:
- The two hooks, short enough to read in a minute. On Cursor CLI and Gemini
CLI they run through
hooks/adapter.sh. - Two small scripts, which
os-big-pictureandos-what-could-go-wrongcall. The second is loaded through a!command, which is a Claude Code feature. How other tools handle that line is indocs/other-agents.md. - The install check,
doctor.sh, when you run it.
The skills also have the agent run git and gh commands, including merges,
as What it does on its own says.
The hooks
Two hooks ship with the pack. The Claude Code plugin connects them for you. On
Codex CLI, Cursor CLI and Gemini CLI you wire them by hand, as
docs/other-agents.md shows.
session-start.sh puts the routing table and the
last report in front of a new session. It also quietly records what your
repositories looked like at that moment.
stop-report.sh compares against that when the
session ends, and asks for a report if real work landed. That is also how work
you finished inside a single reply still gets one. Neither hook can loop:
reports are written outside your repositories, so writing one changes nothing
they look at. The stop hook costs nothing when it stays quiet. The start hook
does add its text to your context, with the report part capped by the setting
below. Their settings:
| Setting | Default | What it does |
|---|---|---|
OPEN_STEPS_COOLDOWN | 900 | seconds of quiet between report requests |
OPEN_STEPS_MIN_FILES | 1 | changed files before a report is asked for |
OPEN_STEPS_MAX_REPOS | 25 | started in a folder of repositories, how many get checked |
OPEN_STEPS_DISABLE | unset | set to anything to switch the stop hook off |
OPEN_STEPS_MAX_REPORT_LINES | 80 | cap on the last report the start hook shows |
OPEN_STEPS_NO_SESSION_START | unset | set to anything to switch the start hook off |
Reports are saved outside your repositories, in
~/.claude/open-steps/reports/<project>/. So they stay out of your commits
and survive uninstalling the pack. Each tool is pointed at this one folder, so
all your tools share one history. The .claude in the path is only a name.
Three decisions
These shape everything here:
- Descriptions are commands, not summaries. The skill descriptions open with "ALWAYS invoke this skill…". With this form the skills switched on in the test runs shown under Numbers. The evals do not compare it with other wordings.
- A skill cannot force itself to run. Anything that must hold in each
reply lives in the tool's standing instructions file (
CLAUDE.md,AGENTS.md,GEMINI.md) or, on Claude Code, the output style instead. The pack says which layer each piece belongs to. - Measured and assumed stay apart. A "yes" has to name its proof. Anything unchecked says "not checked". This is also why the reports are short: the agent stops narrating its checks and states the result.
The plain-language rules borrow from ASD-STE100, the simplified English written for aerospace manuals: short sentences, active voice, one idea per sentence. Borrow is the word. Nothing here is certified against the standard.
Limits
- Answer quality and the premortem's fresh agent are measured on Claude Code only. What was run on each tool is under What was run on each tool.
- The output style does not reach subagents. So
os-what-could-go-wrongcarries its rules inside the handover to its fresh agent, and its plain language rests onreferences/premortem-prompt.md.
Open source
Free, MIT licensed. Take it, use it at work, change it, fork it.
I keep building this pack for my own work, so it moves on its own. Pull requests are welcome and I read them; the rules are in CONTRIBUTING.md.
If it helped, a star makes it easier for other people to find.
License
MIT. See LICENSE. © 2026 Pavlo Kharmanskyi.
Open Steps is an independent open-source project, not affiliated with or endorsed by the makers of the tools it runs on. Claude and Claude Code are trademarks of Anthropic. All other trademarks, including Codex, Cursor and Gemini, are the property of their respective owners.